Loading
Next.js 15Vercel AI SDKGroq APITailwind CSSTypeScript
AI Chatbot UI
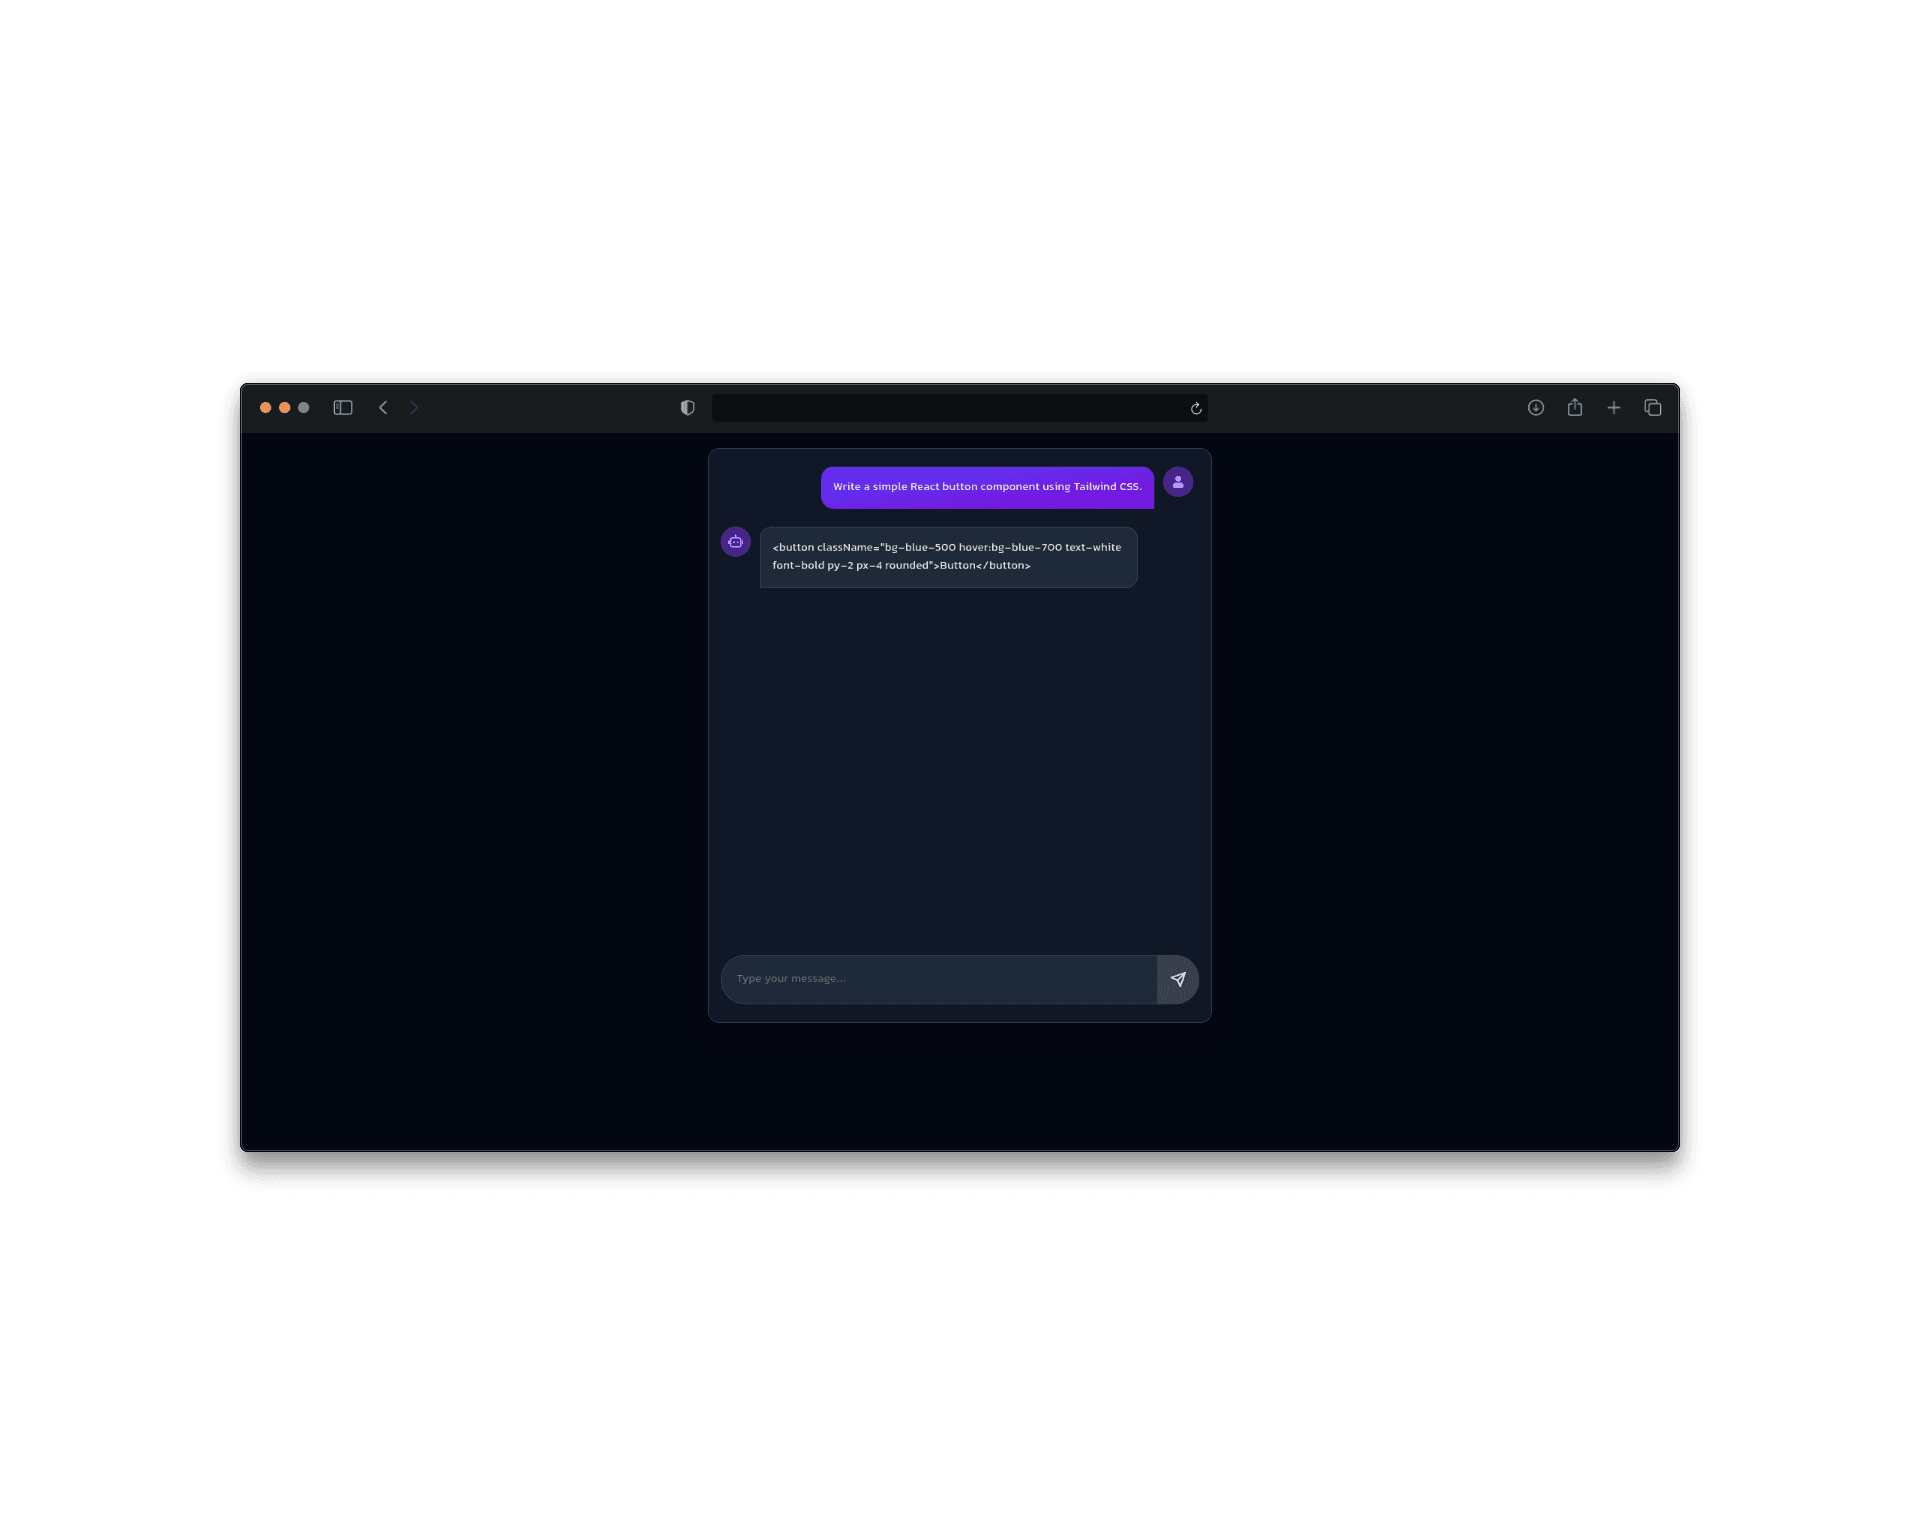
A developer-focused AI conversational platform highlighting modern streaming ergonomics. It provides low-latency token rendering, automatic scroll anchoring, and syntactically highlighted code blocks with one-click copy tooling.
Project Info
RoleFrontend Engineer
Timeline2 Weeks
Core Tech
Next.js 15Vercel AI SDKGroq APITailwind CSSTypeScript
The Challenge
Preserving user scroll position during high-speed LLM streaming output, especially when auto-formatting Markdown code fences.
The Solution
Engineered intelligent scroll anchoring that pauses auto-scrolling if the user scrolls up, and utilized the Vercel AI SDK to consume SSE streams without freezing concurrent UI thread tasks.
Ultra-low Latency Token Streaming via Groq API
Syntax Highlighting with Copy-to-Clipboard Buffers
Smart Sticky-to-Bottom Scroll Anchoring
Accessible, Screen-Reader Ready Conversation Log
System Architecture & Data Flow
Edge Streaming01
Edge Runtime Proxy
Streams response bytes directly to the client without node server buffering.
DOM Parser02
Memoized Markdown Pipeline
Parses incoming markdown chunks incrementally without full-tree re-evaluation.
Scroll Observer03
Dynamic Scroll Anchor
Calculates user intent from scroll velocity before triggering automatic down-snaps.
Key Impact & Outcomes
- Time to First Token (TTFT)
- < 180ms
- Render Lag on Code Blocks
- Zero Stutter
- Accessibility Compliance
- WCAG 2.2
Engineered minimal-overhead edge route proxying to Groq endpoints.
Memoized syntax highlighting tokens to prevent repetitive parsing passes.
Integrated polite live-regions for real-time screen-reader accessibility.
Performance Benchmarks (Before vs. After)
Token Stream Latency-81%
Before950ms
After180ms
Main-Thread Frame Time-76%
Before38ms
After9ms
Script Evaluation Time-77%
Before180ms
After40ms
Engineering Decisions & Trade-offs
Vercel AI SDK text streams over custom WebSocket connections
Server-Sent Events (SSE) provide built-in HTTP/2 multiplexing and auto-reconnection without the overhead of dedicated socket servers.
Lightweight Prism.js highlighter over heavy Shiki server compilers
Prism allowed fast client-side stream chunk highlighting without incurring severe server hydration payload weights.
Interface Showcase
Interactive inspection of high-fidelity views
chatbot-ai-delta-ochre.vercel.app
Click to expand