Loading
Next.jsTypeScriptZustandCKEditor 5Tailwind CSS
Chapchin AI Assistant
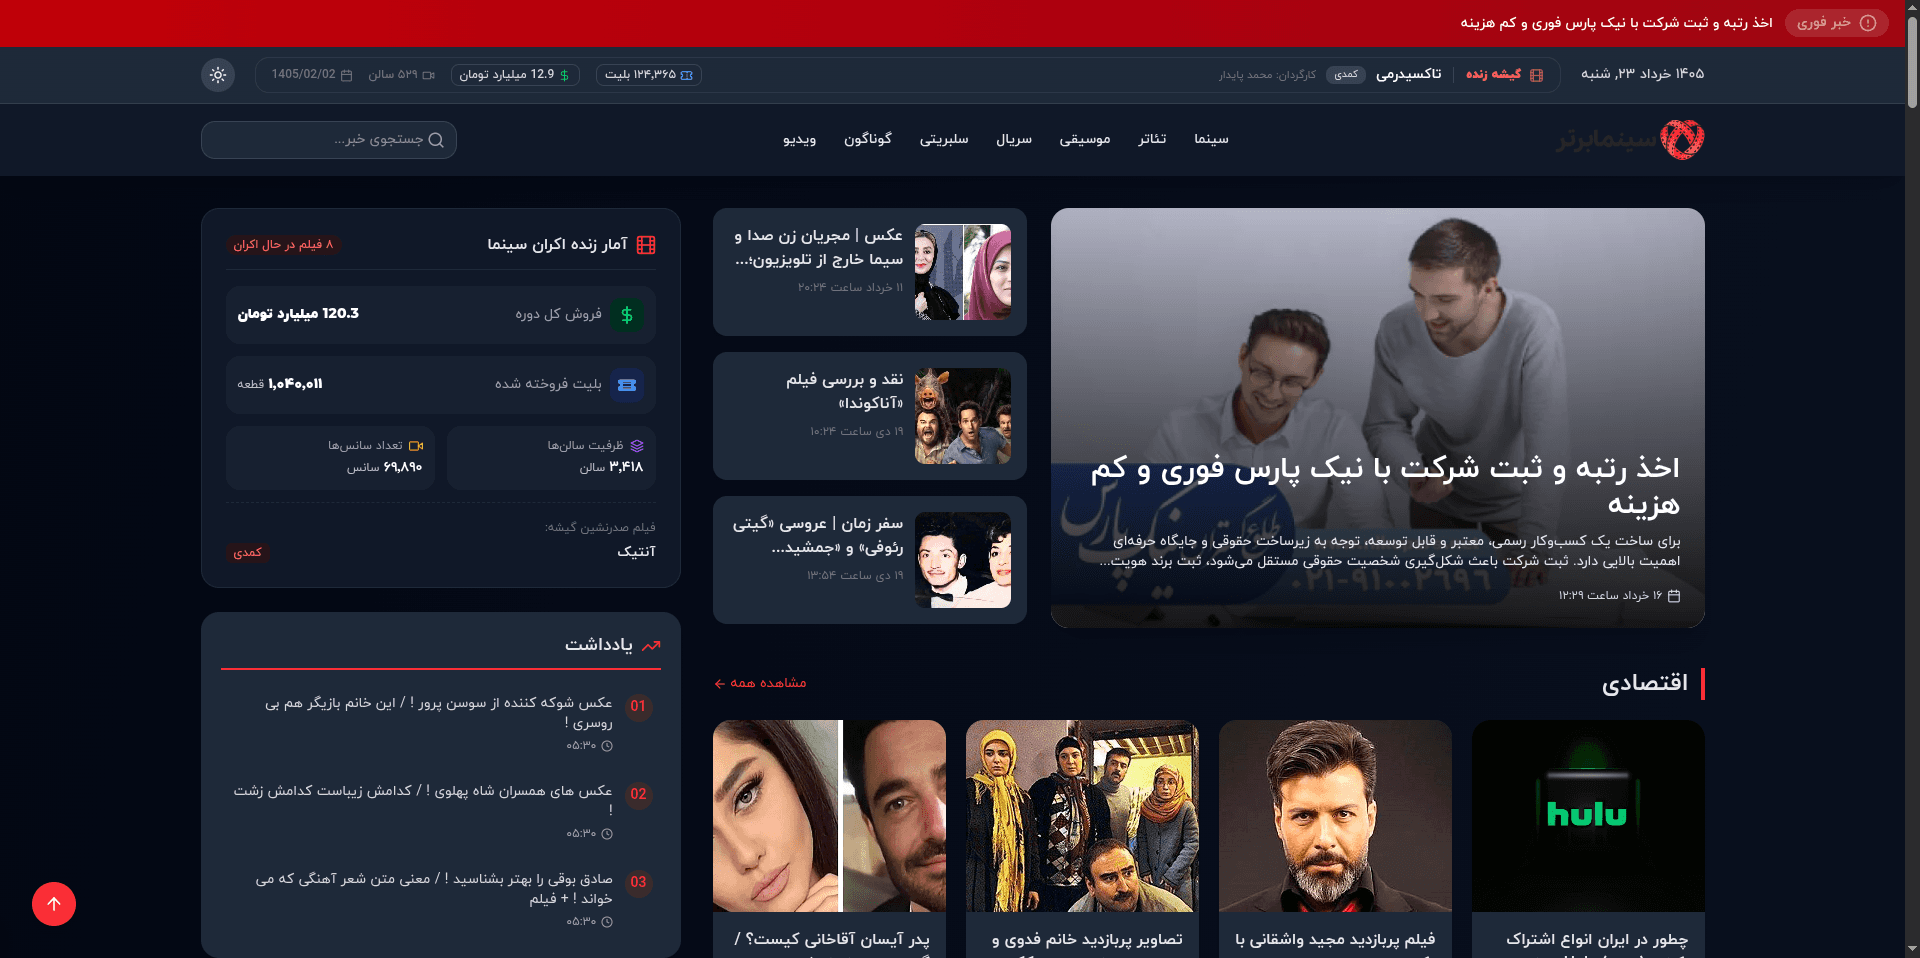
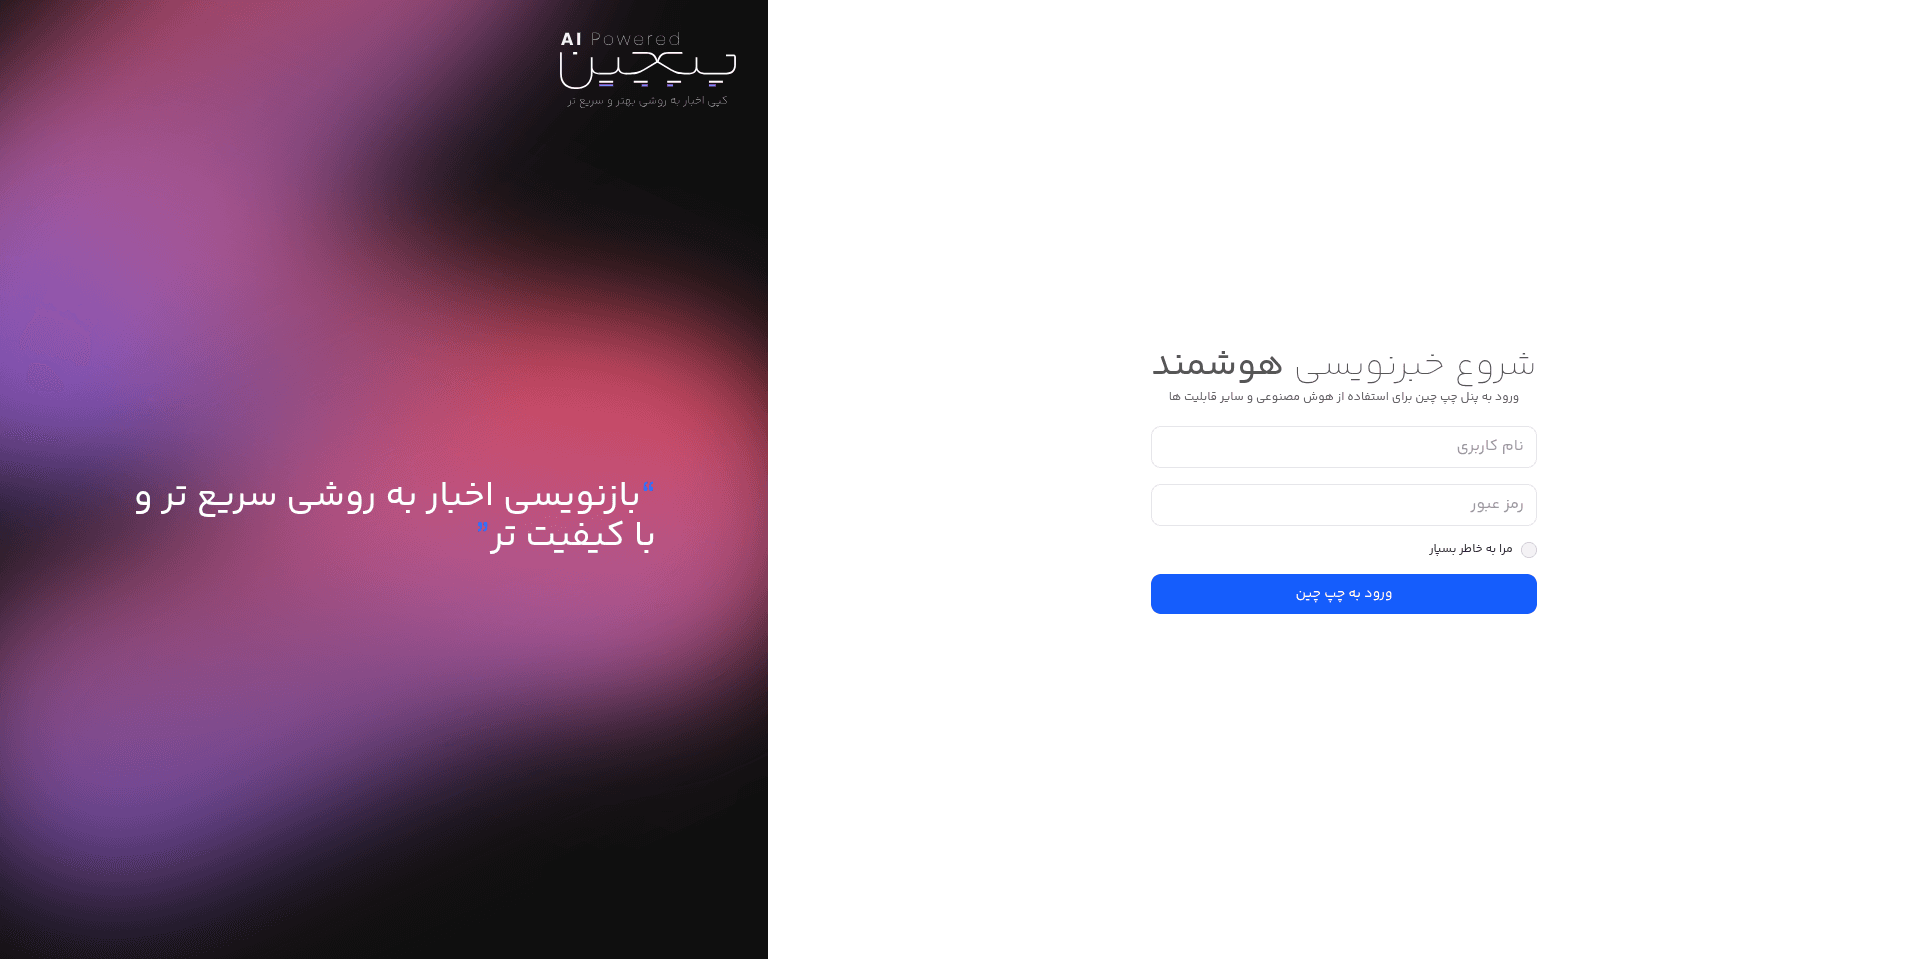
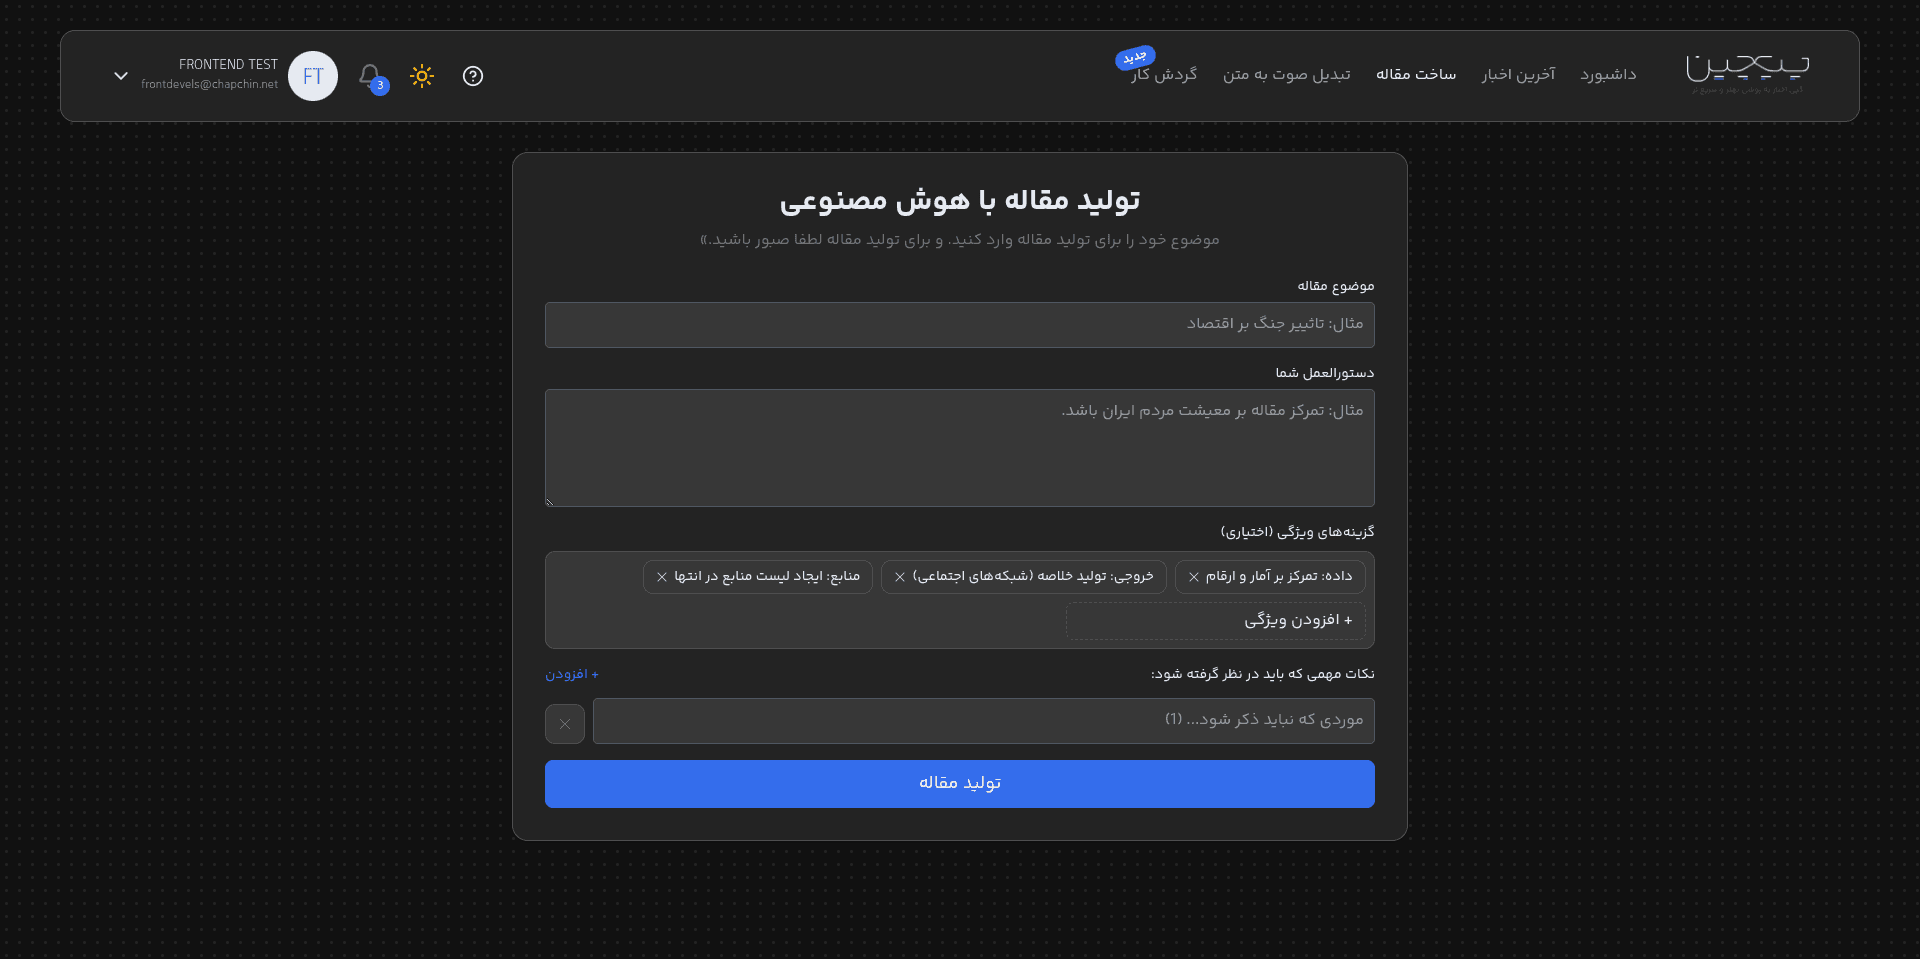
Chapchin eliminates writer's block for journalists by pairing rich-text composition with contextual AI generation. It orchestrates prompt chaining, headline brainstorming, and live editorial feedback within an enterprise WYSIWYG environment.
Project Info
RoleLead Frontend Engineer
Timeline4 Months
Core Tech
Next.jsTypeScriptZustandCKEditor 5Tailwind CSS
The Challenge
Consuming high-frequency LLM streaming tokens inside a heavy WYSIWYG editor (CKEditor 5) without triggering continuous main-thread layout thrashing or typing latency.
The Solution
Architected an asynchronous streaming buffer decoupled from the primary React state tree. Batched DOM updates via requestAnimationFrame and offloaded heavy image cropping to client-side Web Workers using Cropper.js.
Non-blocking SSE AI Token Streaming
Client-side Canvas Image Cropping & Optimization
Custom CKEditor 5 Modular Plugin Integration
Optimistic Autosave with Conflict Recovery
System Architecture & Data Flow
Edge Layer01
Next.js Middleware
Performs fast token inspection and geo-routing across regional CDN nodes.
Stream Broker02
SSE Pipeline
Consumes raw token streams through an isolated buffer without blocking UI rendering.
State Hydration03
Zustand Store
Batches state dispatches through requestAnimationFrame to sustain 60 FPS typing.
Key Impact & Outcomes
- Lighthouse Score
- 98/100
- Editorial Speed
- 3x Faster
- Bundle Overhead
- -35%
Deterministic Web Vitals verified on simulated 4G mobile profile.
Reduced average draft composition time from 45 to 15 minutes.
Dynamic chunking verified via @next/bundle-analyzer.
Performance Benchmarks (Before vs. After)
Largest Contentful Paint (LCP)-65%
Before3.4s
After1.2s
Main-Thread Blocking Time-89%
Before420ms
After45ms
Initial JavaScript Bundle-60%
Before310 KB
After125 KB
Engineering Decisions & Trade-offs
Decoupled AI stream buffer from React root tree
High-velocity token dispatch triggered 45+ re-renders per second. Decoupling the stream preserved smooth editor interaction.
Client-side Canvas Image Manipulation (Cropper.js)
Eliminated upload bandwidth roundtrips, reducing editorial wait time and infrastructure operating costs.
Interface Showcase
Interactive inspection of high-fidelity views
app.chapchin.net
Click to expand